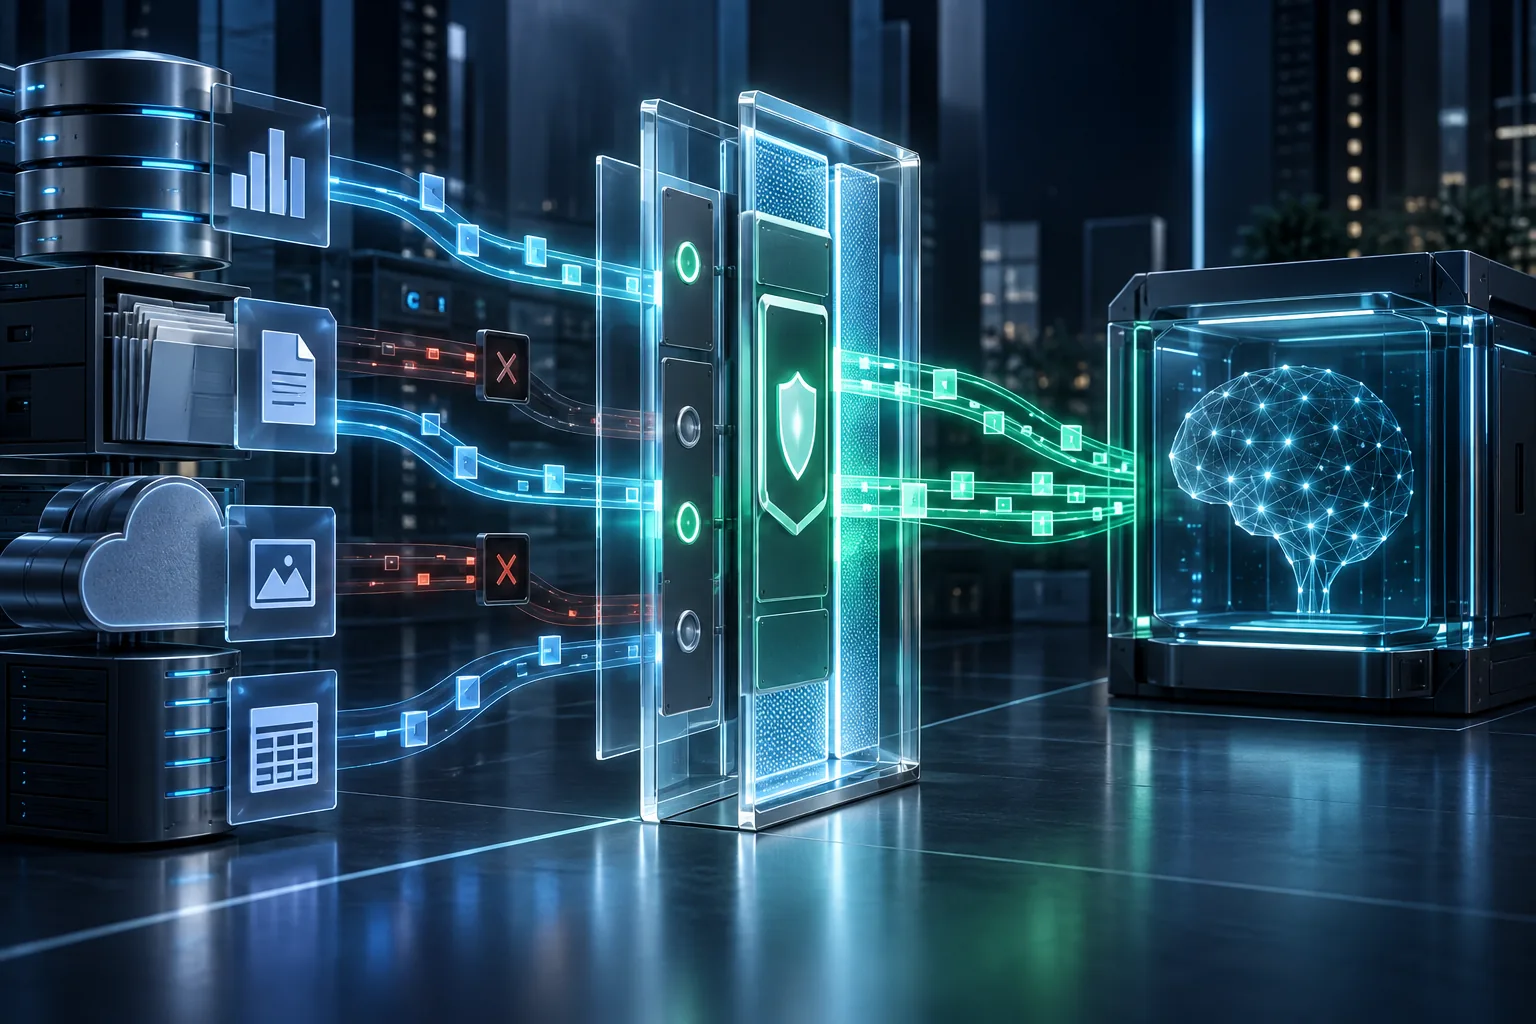
The first security question many business leaders ask is simple: can we connect AI to our company data without exposing confidential information?
The answer is yes, but access should never begin with the entire shared drive, mailbox, customer database, or document library. An AI application should receive the minimum information and capabilities required for one approved business task. It should also respect the same identity, permissions, retention, and audit rules that govern the original system.
This matters because the useful part of business AI is also the sensitive part. A public chatbot can answer questions from a website. A genuinely useful internal assistant may need policies, product information, contracts, customer records, service history, or operational data. The closer the AI gets to real work, the more deliberately its access must be designed.
For UAE organisations, the issue is not only cybersecurity. The UAE Personal Data Protection Law establishes controls for electronically processing personal data, obligations to protect confidentiality and privacy, individual rights, and requirements affecting cross-border transfers. Sector rules, contractual obligations, DIFC or ADGM requirements, and client policies may add further responsibilities. This article provides practical operational guidance, not legal advice.
AI access is not a yes-or-no decision
Asking whether AI can access company data is too broad. A useful decision separates five questions:
- Which user is asking?
- Which information is required for the task?
- What is the AI allowed to do with that information?
- Where will the information be processed and retained?
- How will the organisation detect misuse, errors, or excessive access?
The same document may be appropriate for one person and prohibited for another. A finance policy may be available to every employee, while payroll records should remain restricted to authorised HR and finance roles. A sales employee may be permitted to see assigned customer accounts but not every customer in the CRM.
The AI must not become a shortcut around those boundaries.
Map the complete data journey
Security reviews often focus only on the model provider. The complete path is wider:
Secure data path: Employee identity → application policy check → permission-aware retrieval → data minimisation → model processing → output validation → human approval or controlled action → audit log.
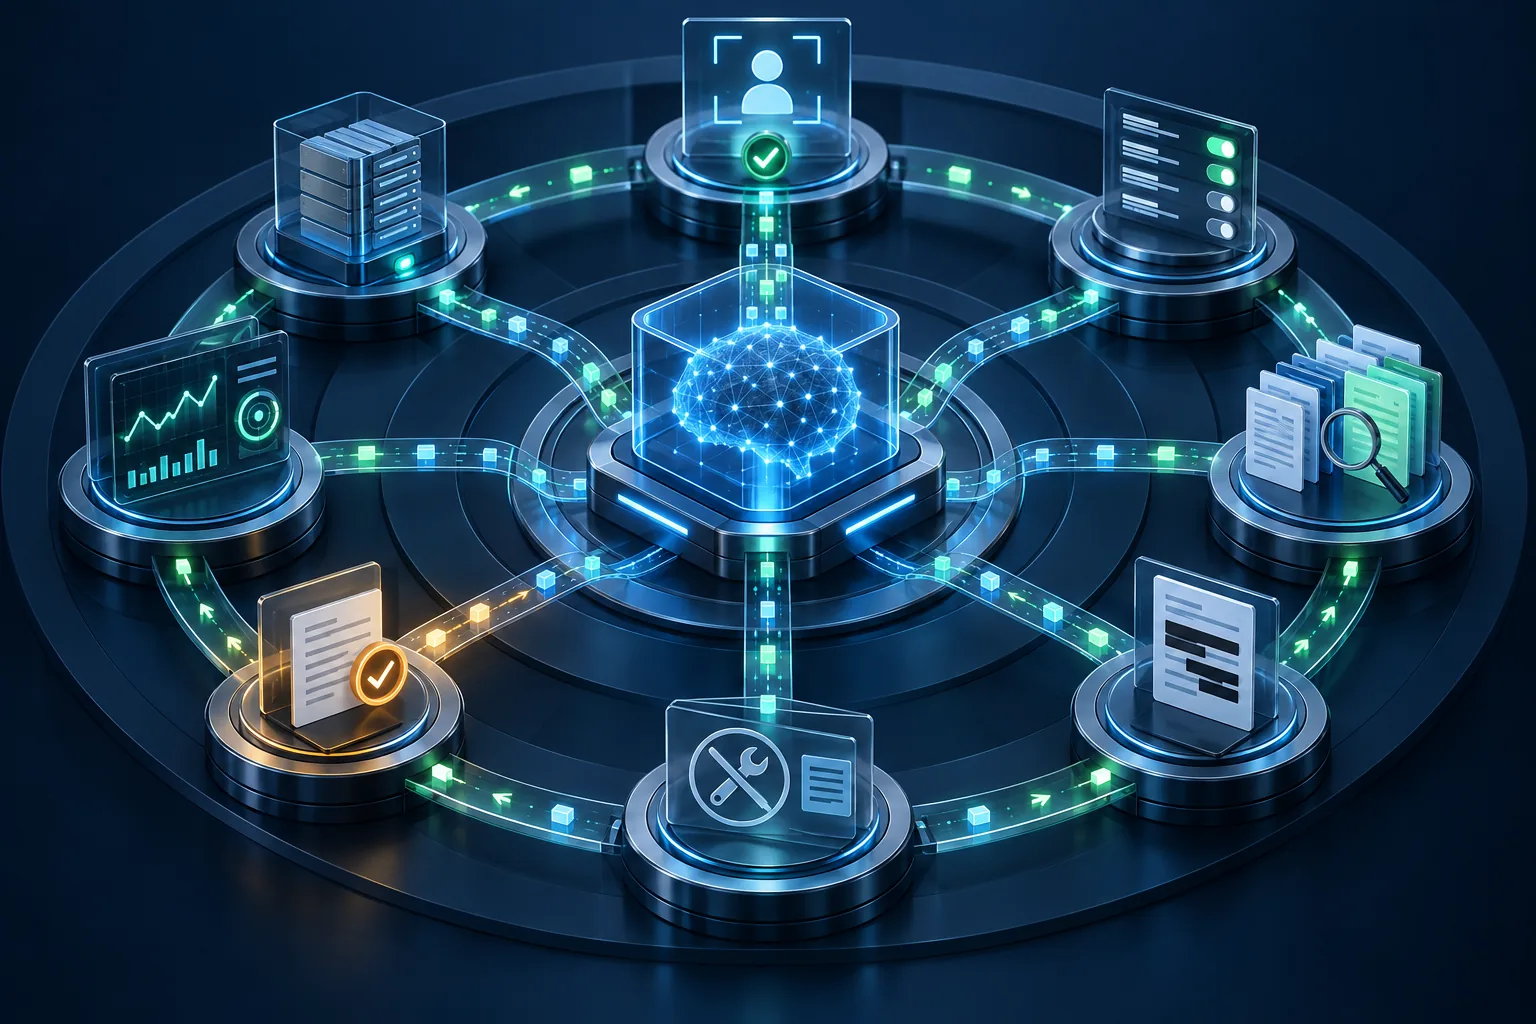
Information may be exposed through the user interface, browser extensions, application logs, integration platforms, retrieval indexes, model requests, generated responses, connected actions, analytics tools, support systems, and backups.
A responsible design documents each stage. The team should know what data enters the system, why it is needed, where it travels, who can retrieve it, how long it remains, and how it is removed.
What should AI be allowed to read?
The practical answer begins with data classification and task necessity.
| Information | Starting position | Recommended control |
|---|---|---|
| Public website content | Normally allowed | Use approved and current sources. |
| Internal policies and procedures | Role controlled | Limit access to authorised employees and return citations. |
| CRM customer records | Purpose limited | Retrieve only required fields and permitted accounts. |
| Contracts and legal documents | Restricted | Use controlled access, audit logs, and approved retention. |
| HR and payroll records | Highly restricted | Isolate by role and documented purpose. |
| Health, biometric, or identity data | Exceptional access | Require privacy, security, and legal review. |
| Payment-card information | Do not expose directly | Keep it inside compliant payment systems. |
| Passwords, API keys, and private keys | Never provide to the model | Use a secrets manager and controlled service calls. |
| Entire mailboxes or shared drives | Avoid broad access | Use permission-aware retrieval for the current task. |
These are starting positions, not universal legal conclusions. A customer name may be necessary for an authorised service agent but unnecessary for a model classifying complaint themes. Where identity is not needed, data can be aggregated, redacted, or tokenised before processing.
Information AI should not receive by default
Some information should remain outside prompts and general-purpose knowledge stores unless there is a documented requirement and a specifically controlled design.
Passwords, keys, and security secrets
Passwords, API keys, private certificates, recovery codes, database credentials, and production secrets should never be pasted into prompts or indexed as reference material. They belong in an approved secrets-management system. The AI application should call a controlled service without seeing the underlying credential.
Unfiltered database exports
Giving an assistant a full customer, HR, finance, or operational export is rarely necessary. Query only the required fields and rows after checking the user's identity and purpose.
Entire mailboxes and shared drives
Broad access creates a large and constantly changing risk surface. The system should retrieve a small set of relevant items using the user's existing permissions rather than copying everything into one unrestricted AI index.
Sensitive information without a defined purpose
Health information, identity documents, biometric data, payment information, employee investigations, privileged legal material, and confidential transactions require a much higher threshold. If the task can be completed without the sensitive fields, remove them.
Data kept only because it may be useful later
AI does not remove the need for data minimisation. Collecting or retaining additional information without a defined use increases privacy, security, and operational risk.
Reading data is different from taking action
An assistant that reads an approved policy and cites the relevant paragraph presents one risk level. An agent that changes a customer record, sends an email, approves a discount, releases a payment, or deletes a document presents another.
OWASP guidance on excessive agency identifies three recurring causes of harm: excessive functionality, excessive permissions, and excessive autonomy. A secure implementation reduces all three.
Begin with read-only access wherever possible. Add write capabilities one at a time, using narrow API functions rather than broad administrator access. High-impact actions should require deterministic validation and human approval outside the model.
A customer-service agent, for example, may be allowed to:
- Read approved product and policy information
- Retrieve the requesting customer's open case
- Draft a response for an employee
- Suggest the correct routing category
It should not automatically be allowed to:
- Search every customer's records
- Change a contract or entitlement
- Issue an unlimited refund
- Email an external address without confirmation
- Export a list of customer details
- Delete the conversation history
Ten controls that protect company data when using AI
1. Classify information before connecting it
Use categories that employees can understand, such as Public, Internal, Confidential, and Restricted. Define which AI environments and use cases are permitted for each category. The policy should name examples, owners, exceptions, and approval routes.
2. Use enterprise-managed AI services
Consumer and enterprise services can have different administration, contractual, retention, and training arrangements. Confirm whether submitted content is used for training, how long it is retained, which subprocessors receive it, where it is stored, and how it can be deleted.
No model training and zero retention are different commitments. Neither should be assumed from a product name or marketing statement.
3. Enforce identity and least privilege
Connect the application to the organisation's identity provider. Use single sign-on, multi-factor authentication, role-based or attribute-based access, and short-lived credentials. The AI should operate within the requesting user's permissions or a more restrictive service identity.
4. Preserve permissions during retrieval
A retrieval-augmented generation system can find relevant passages from approved sources before asking the model to answer. However, retrieval is secure only when it preserves document, record, and user permissions.
The retrieval service should filter results before model processing, return source citations, remove access when source permissions change, and prevent one user from retrieving another user's material.
5. Minimise, redact, or tokenise data
Send only the fields required for the task. Replace direct identifiers when the model needs a pattern rather than a person's identity. Mask sensitive values in prompts, responses, logs, and test datasets.
6. Apply data-loss prevention controls
DLP rules can detect personal information, financial records, source code, credentials, contract terms, and large exports before data reaches the model. Output controls can also prevent sensitive material from being returned to an unauthorised user or external destination.
7. Separate trusted instructions from untrusted content
An email, webpage, PDF, image, or uploaded document may contain malicious instructions aimed at the AI. OWASP's prompt-injection guidance explains that external content can manipulate model behaviour and that retrieval alone does not remove this risk.
Treat retrieved content as data, not as authority. Keep system rules separate, constrain available tools, validate actions in ordinary application code, and require approval for privileged operations.
8. Encrypt data and control the network path
Use encryption in transit and at rest, managed keys where required, approved regions, private network connectivity where appropriate, and restricted administrative access. Data residency can support a compliance strategy, but location alone does not make an AI system secure.
9. Record access and actions
Audit logs should show who used the AI, which sources were accessed, which tools were called, what action was requested, whether a human approved it, and whether a policy blocked the request.
Logs can themselves contain confidential prompts and responses, so they need access controls, retention limits, and monitoring.
10. Test continuously
Test normal use, permission boundaries, prompt injection, data extraction attempts, malicious documents, unusual volumes, revoked access, incorrect model output, and failed integrations. Review controls again whenever a new data source, model, tool, or autonomous action is introduced.
The NIST AI Risk Management Framework provides a useful structure for governing, mapping, measuring, and managing AI risks across the system lifecycle.
Questions to ask an AI provider
Before approving an AI service or implementation partner, obtain clear answers to these questions:
- Is our data used to train any shared model?
- What information is retained, for how long, and for what purpose?
- In which country or region is each type of data processed and stored?
- Which subprocessors and support personnel may access it?
- Can we select or restrict the processing region?
- How are tenant data and retrieval indexes separated?
- Does the platform support our identity provider and granular permissions?
- Can administrators disable connectors, sharing, memory, and external actions?
- Are prompts, responses, retrieved documents, and tool calls included in audit logs?
- How can records be corrected, exported, deleted, or placed under legal hold?
- What happens to our information when the contract ends?
- How are security incidents reported and investigated?
A vendor questionnaire is not a substitute for architecture review. The organisation must also examine the application, integrations, configuration, and operating process built around the model.
A practical deployment pattern
A secure internal AI assistant commonly follows this sequence:
- The employee signs in through the company identity provider.
- The application checks the employee's role and current permissions.
- A policy layer decides whether the request and data category are permitted.
- The retrieval service searches only sources the employee can access.
- Sensitive fields are removed when they are unnecessary.
- The model receives the smallest useful context.
- The response is checked for policy violations and supported with source citations.
- Any consequential action is validated and, where required, sent for human approval.
- Access, sources, output, approvals, and actions are written to protected audit logs.
This architecture does not make every risk disappear. It limits the impact of mistakes and makes the system governable.
AI data security checklist for business leaders
Before go-live, confirm that the organisation can answer yes to the following:
- We have named the business owner, data owner, technical owner, and security owner.
- The use case has a specific purpose and measurable outcome.
- The connected data has been classified.
- Access follows the user's existing permissions or stricter rules.
- The AI does not receive credentials or unnecessary sensitive fields.
- Training, retention, location, and deletion terms are documented.
- Read and write capabilities are separated.
- High-impact actions require validation and approval.
- Prompt injection and data-extraction scenarios have been tested.
- Logging, monitoring, incident response, and periodic access review are in place.
- Employees know which AI tools and information categories are approved.
- Legal, privacy, contractual, and sector requirements have been reviewed.
If several answers are no, the solution is not ready for sensitive business data.
Frequently asked questions
Does an enterprise AI service train on our company data?
That depends on the provider, product, contract, configuration, and feature. Confirm the terms for prompts, uploaded files, retrieval indexes, logs, feedback, and support access. Do not assume that every service from the same provider handles data identically.
Does keeping AI data in the UAE make it secure?
Data residency addresses where information is stored or processed. Security also depends on identity, permissions, encryption, application design, retention, monitoring, administrative access, and incident response. Residency is one control, not the complete solution.
Is a private AI model automatically safer?
No. A privately hosted model can still expose information if the application retrieves the wrong records, users have excessive permissions, logs are unprotected, or an agent can take unsafe actions. Private hosting changes part of the risk model but does not replace security engineering.
Can AI search SharePoint or a CRM without seeing everything?
Yes. The integration can use the signed-in user's permissions or a restricted service account, apply record-level filters, and retrieve only the information needed for the current request. Permission-aware retrieval must be designed and tested explicitly.
Should an AI agent have permission to update business systems?
Only when the business benefit requires it. Start with read-only access, expose narrow actions, validate every input, apply transaction limits, and require human approval for sensitive or irreversible changes.
Secure AI starts with a clear access design
The safest answer is not to keep all company data away from AI. That would also prevent many useful applications. The answer is to connect the right information to the right task under the right identity, with controls that remain effective when the model makes a mistake or encounters malicious content.
TechnoSignage helps UAE and GCC organisations classify AI data access, assess vendors, design permission-aware retrieval, integrate business systems, introduce human approvals, and deploy AI applications with monitoring and operational ownership.
Discuss an AI data access and security assessment with our team, or explore our AI consulting services and custom AI application development.